Sydney Data, Overseas Answers

Release date:
Hero Vector
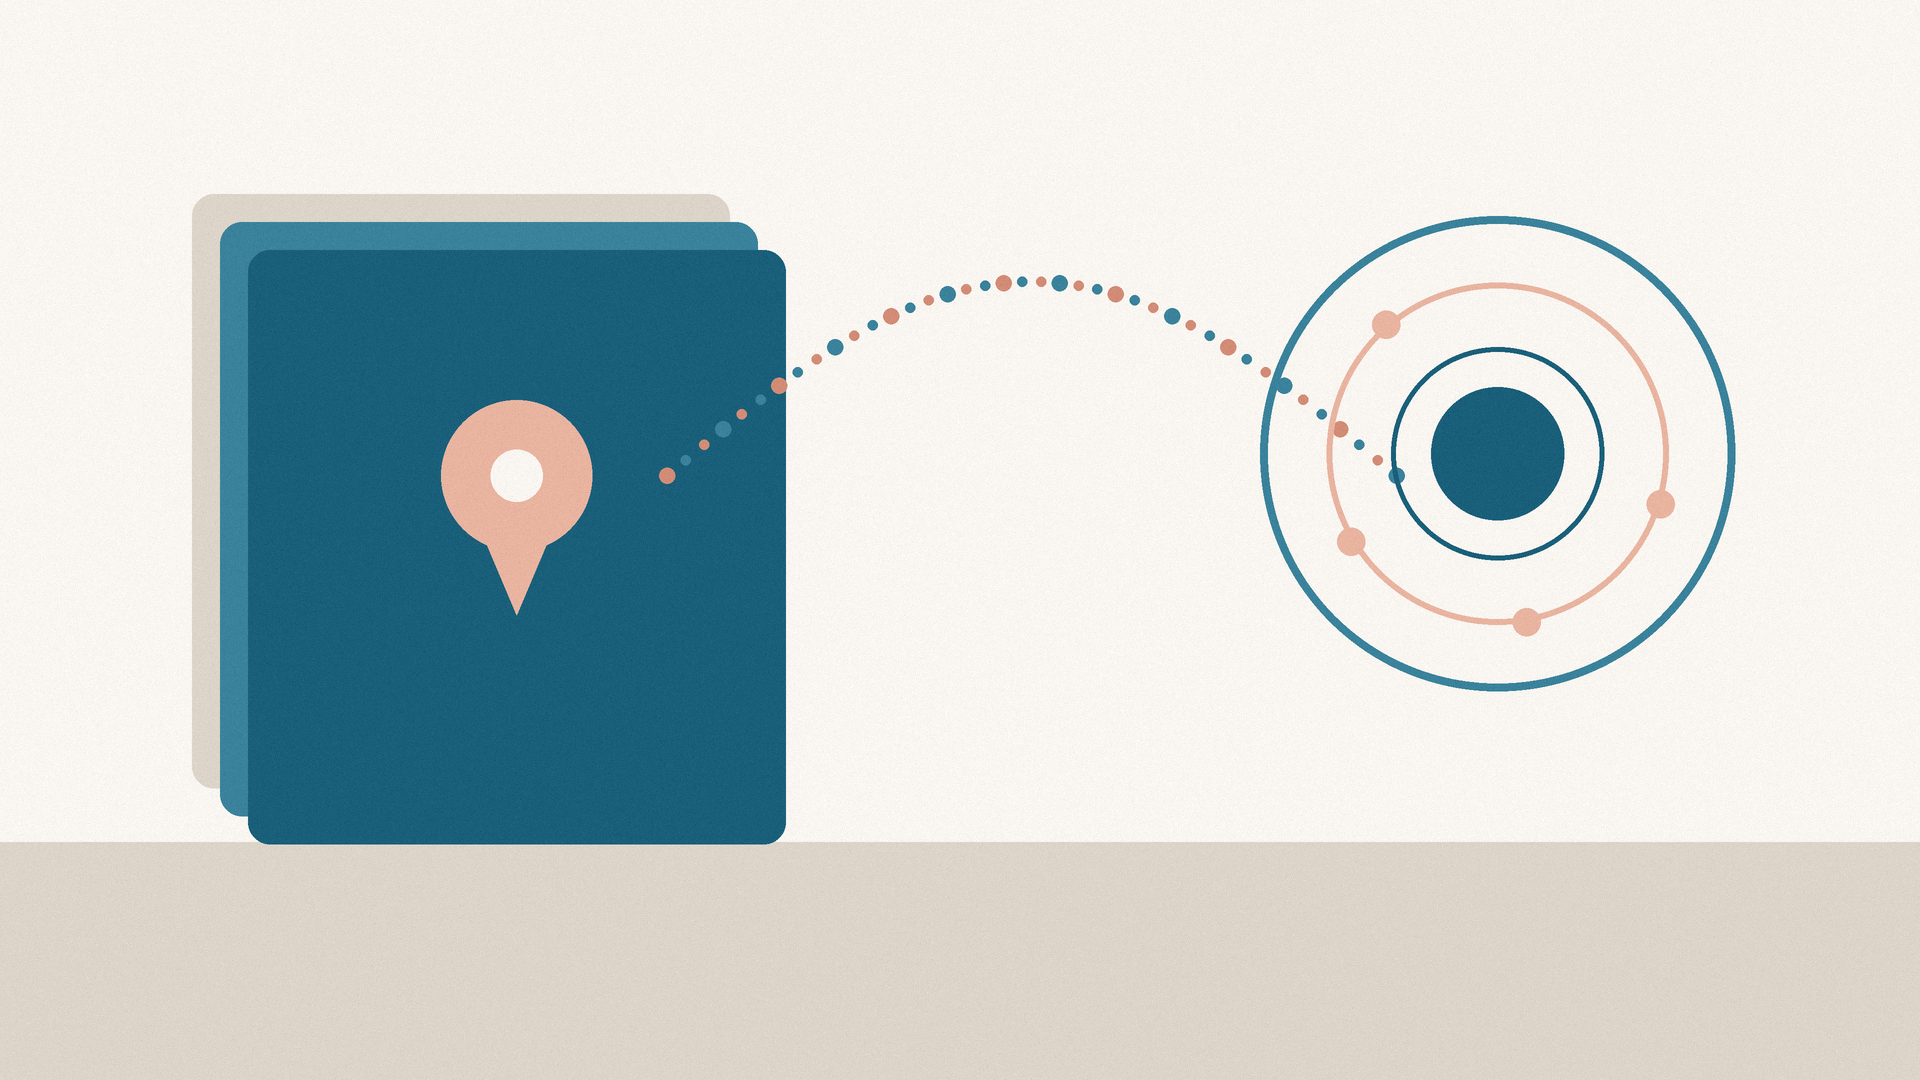
Abstract teal local data panels with a soft location pin on cream, linked by a dotted arc to a distant apricot and teal orbital shape suggesting overseas model answers
Vector ImageVector ImageVector Image
Blog detail
Vector ImageVector ImageVector Image

The architecture diagram looks tidy. Customer data lives in Sydney. The vector store is in an Australian region. The privacy impact assessment says personal information does not leave the country. Then someone traces a single answer and finds the prompt left Australia in under a second.

That gap is showing up in a lot of Australian AI programmes right now. Teams treat data residency as a storage question. Inference is a different journey. The records stay put. The content that actually goes into the model often does not.

If your board asked "where does customer data go when someone asks the AI a question?", would the honest answer match the slide?

Residency on the Diagram, Not on the Wire

Most enterprise AI stacks already keep source systems and warehouses in Australian regions. That is the easy part. The hard part starts when a user asks a question and the platform builds a prompt.

A typical flow looks like this:

  • Retrieve a handful of chunks from a local index.
  • Attach recent chat turns, tool results and system instructions.
  • Send the whole package to a model endpoint.
  • Return an answer that may include paraphrased customer detail.

If that model endpoint is in another country, the prompt payload just travelled. Embeddings for new documents, batch evaluations and agent tool loops do the same thing at scale. Storage never moved. The sensitive content still did.

Vendors often describe this as "your data is not used for training." That is a training promise, not a residency promise. Processing location, logging, support access and subprocessors are separate questions, and they are the ones Australian privacy teams care about when something goes wrong.

What Actually Leaves

Teams that map the wire usually find more leaving than the first architecture review assumed:

  • Retrieved context. Chunks pulled for RAG often contain names, account numbers, case notes or policy text. Those chunks sit inside the prompt.
  • Conversation history. Multi-turn chats accumulate personal detail even when each single turn looks mild.
  • Tool outputs. An agent that reads CRM, billing or HR systems can ship those responses straight into an overseas model call.
  • Evaluation sets. Offline evals built from real tickets are frequently run against the same remote endpoints used in production.
  • Logs and traces. Prompt and completion logging for debugging can retain content in vendor regions long after the answer was shown.

None of this means overseas models are off limits. It means "data stays in Australia" is incomplete if it only describes where the database lives.

Ask the Questions Storage Diagrams Skip

Before you call a use case residency-safe, answer these in writing:

  1. Where does inference run for this workload? Name the region, not just the vendor.
  2. What exactly is in the prompt? System instructions, retrieved chunks, memory, tool results and user text all count.
  3. Who can see prompts and completions? Vendor support, your own ops team, observability tools and secondary logging destinations.
  4. What is retained, for how long, and where? Include failed requests, traces and eval runs.
  5. What happens on failover? A secondary region outside Australia can quietly become the real path under load.
  6. Does the privacy notice match the design? If customers were told processing stays onshore, overseas inference needs a clear explanation and a decision, not a quiet exception.

Those answers belong next to the architecture diagram, not in a side chat with the platform team.

Practical Patterns That Hold Up

Australian organisations that handle this well tend to mix controls rather than chasing a single checkbox:

  • Prefer regional endpoints when the use case needs them. For customer service, HR, health-adjacent and regulated workloads, onshore or explicitly approved regions should be the default, not an optional upgrade.
  • Minimise what you send. Redact identifiers, summarise tool results before they enter the prompt, and keep retrieval tight. Smaller prompts are easier to justify and cheaper to run.
  • Separate public workloads from sensitive ones. Marketing copy and internal brainstorming can use a different path from case notes and customer accounts.
  • Keep eval data under the same rules as production. A golden set full of real tickets should not get a free pass because it is "just testing."
  • Instrument the path. Log destination region, token counts and whether personal data classes were present, without dumping full prompts into a second overseas system.

The aim is not to ban every cross-border call. It is to make the crossing deliberate, documented and matched to the risk of the content.

How TruFyre Helps

At TruFyre we help Australian organisations design AI platforms where residency claims survive contact with the real request path. That includes mapping what leaves on every prompt, choosing regional inference where it matters, tightening retrieval and tool payloads, and aligning privacy notices with how the system actually runs.

If your storage is in Sydney and your answers are coming from somewhere else, talk to us. The fix starts with an honest diagram of the wire, not another slide about the data lake.
BG Image
Vector ImageVector ImageVector Image
We’re here to help
Vector ImageVector ImageVector Image

Ready to put AI to work in your business?

Talk to an AI expert about your goals.
Arrow Icon
Smart process automation
Arrow Icon
Direct access to our team. No bots.
Arrow Icon
We ask smart questions fast.

Book a Discovery Call

Your form has been submitted successfully. Thank you!
Please double-check your information and try again. If the issue continues, email us at info@trufyre.ai